Why Model Benchmarks Don’t Matter in Evaluating AI for eDiscovery
Legal technology procurement teams love public benchmarks. Pitches frequently highlight Massive Multitask Language Understanding scores, reasoning metrics, context window sizes, and bar exam percentiles.
In eDiscovery, those scores are largely irrelevant to operational success.
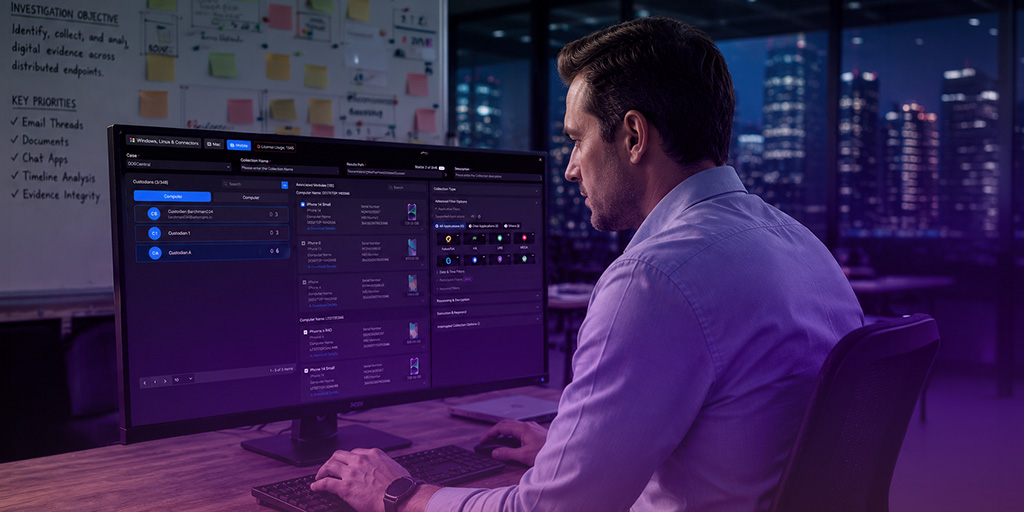
When artificial intelligence moves from drafting deposition summaries to orchestrating legal holds, enterprise preservation, and collections, model intelligence is no longer the bottleneck. The smartest model in the market cannot find evidence it cannot reach. In eDiscovery, data access is not just an infrastructure detail—data access is the AI capability.
Deep data accessibility is just one principle underpinning how to responsibly use agentic AI in eDiscovery workflows. Learn about the others in the Exterro whitepaper, When AI Starts Doing the Work: Six Principles for Governing Agentic AI in eDiscovery.
The Reality of Enterprise Data Fragmentation
An autonomous agent’s reasoning is strictly bounded by the evidence placed in front of it. A model can possess near-flawless semantic comprehension, but it cannot analyze a critical message that was never collected, identify a key custodian whose communications sit outside accessible systems, or deduce facts trapped in unmapped repositories.
The hardest technical challenge in eDiscovery has never been comprehension alone. It is locating and governing information across a fragmented enterprise footprint:
- Ephemeral messaging in Slack and Microsoft Teams.
- Cloud storage platforms like Box, OneDrive, and Google Drive.
- Mobile devices, legacy file shares, and structured databases.
- Shadow IT tools and emerging SaaS applications adopted without legal’s knowledge.
If an AI agent is connected to a frontier model but operates without native data connectivity and access controls, it operates blind. Evaluating legal AI based solely on model benchmarks is like evaluating a litigator based entirely on their law school GPA while denying them access to the case files.
The Downstream Economics of Early Evidence Reach
Data reach is not merely a technical prerequisite; it is an economic driver.
The overwhelming cost of eDiscovery sits in downstream review. When an agentic system possesses governed access to enterprise data sources early in a matter, it can pinpoint relevant communications and eliminate non-responsive noise before processing begins.
Irrelevant data that never enters the review platform does not generate hosting fees, processing costs, or billable reviewer hours. A slightly "smarter" model operating on an uncontrolled data dump will cost exponentially more than a governed orchestration layer that surfaces only the right evidence from the start.
Legal buying teams must shift their inquiries away from generic AI benchmarks and toward operational defensibility. One way to do that is to shift the burden onto vendors early in the buying process. Instead of sitting through a slide deck reciting academic benchmarks, legal teams should ask for live demonstrations of key capabilities before buying:
- Demand to see an actual audit trail from a completed workflow, not a slide summarizing logging capabilities.
The audit log should prove which matter and custodians were involved, which specific instruction set or playbook version was in force, what precise evidence supported the agent's recommendation, who authorized the action, and what downstream steps executed as a result. - Force an exception halfway through an automated task.
Have the vendor show what the system does when a target custodian cannot be mapped to an email account or an endpoint drops offline mid-collection. Does the agent improvise a workaround, continue silently, or safely pause and escalate the issue to a named manager?
The answers to those two demonstrations will tell you more about whether an agentic solution can survive judicial scrutiny under Rule 26(g) and Rule 37(e) than any model accuracy leaderboard ever will.